I Let a 27B Local LLM Build a 3D Game for an Hour. No Hands On.
A local Qwen 27B model at Q4 on one RTX 5090 drove the Pi coding agent for an hour and shipped a playable 3D game, tests and deploy included.
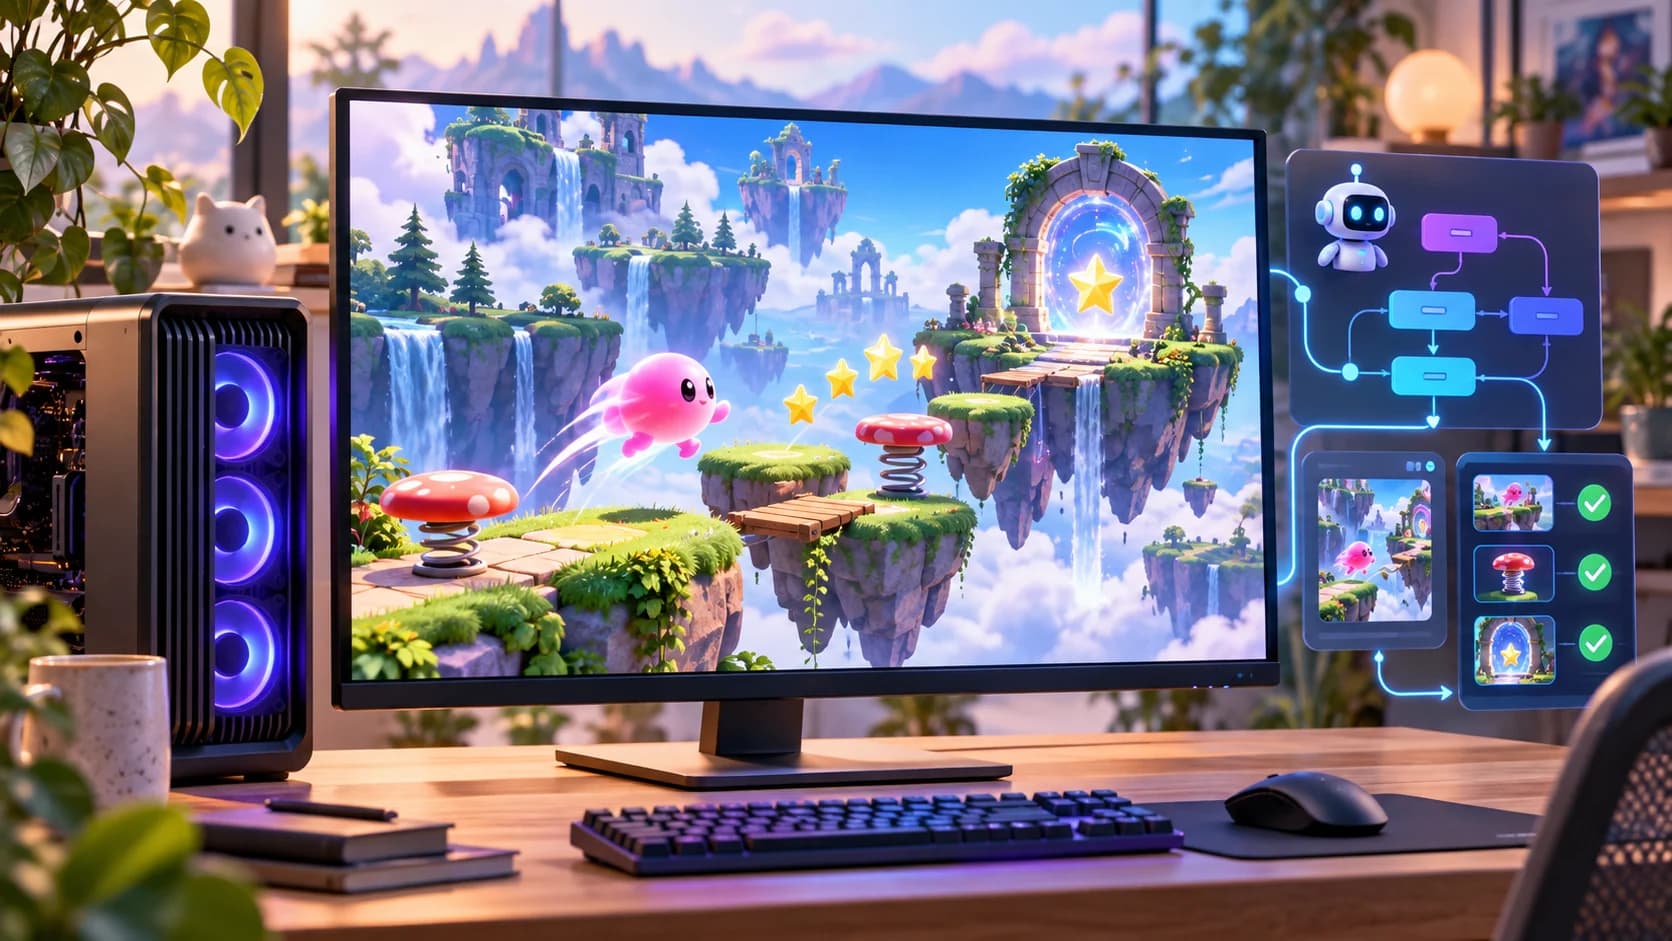
TL;DR: Qwen3.8-27B-GGUF at Q4 quant, running locally on an RTX 5090 through Unsloth, drove the Pi coding agent for about an hour with zero intervention and shipped a complete, playable 3D platformer — physics, art direction, UI, mobile controls, its own test suite, and a Cloudflare deploy. The whole thing. Here's how I set it up, and what surprised me.
The experiment
I wanted to answer one simple question: how good are local LLMs at real agentic coding right now? Not benchmarks, not "write me a fibonacci function" — a full multi-file project where the model has to plan, write, test, debug, and ship on its own.
So I framed it as an experiment with three parts: find a good prompt, build the local inference stack, hand it to an agent — then walk away and see what comes back.
Step 1 — finding the prompt
First I asked ChatGPT to search for the best prompt for something that's a simple yet nice 3D game. It turned up this one — the Jelly Jungle brief: a pink jelly character crossing 13 floating islands using triple jumps and spring mushrooms.
Honestly, it's a perfect test case. Simple enough that a small model can hold it in its head, but rich enough to exercise everything: game physics, procedural 3D world building, camera work, UI, mobile touch controls, even an asset-replacement pipeline. And the brief itself is beautifully written — it reads like a design doc, not a vibe.
Step 2 — the local stack (Unsloth)
I set up Unsloth, pulled Qwen3.8-27B-GGUF in the UD-Q4_K_XL quant, and then fiddled with the settings until I found what I think is the best balance:
| Setting | Value |
|---|---|
| Context length | ~128K |
| KV cache dtype | q8_0 |
| Speculative decoding | MTP (multi-token prediction) |
| VRAM budget | 95% — capped so it won't crash my other running apps |
| GPU memory | ≈ 25.5 GB on an RTX 5090 |
One takeaway from the fiddling: ~128K context is the sweet spot for small agentic coding projects like this — big enough to hold the whole project in its head, small enough to stay fast.
Step 3 — the agent (Pi)
Then I set up Pi, the coding agent harness, pointed it at the local model, dropped the Jelly Jungle brief in front of it, and hit start.
And then… I walked away.
The run: ~1 hour, zero intervention
This is the part that surprised me. For an hour plus, the model worked without a single nudge from me:
- Scaffolded the whole project (Vite + Three.js + vanilla JS — no game engine)
- Wrote fixed-timestep game physics: triple jump, spring mushrooms, spinning candy-bar obstacles, crumbling islands, checkpoints
- Built the entire 3D world procedurally — 13 islands, cloud sea, palm trees, crystals, a finish portal
- Matched the reference UI: title screen, HUD, jump meter, pause/help dialogs, mobile joystick + bounce button
- Wrote its own headless test suite (Playwright + software GL) and verified every mechanic before calling it done
- Deployed the whole thing to a Cloudflare Worker
The end result:
- 🎮 Play it here: jelly-jungle.hungry-path.workers.dev
- ⭐ Full source on GitHub: github.com/jf88888/game-jellyjungle — if you try it and it makes you smile, give the repo a star!
And if you want to compare, the original Jelly Jungle was built with Astra — see this post. Side by side, it's honestly impressive how close a local 27B gets.
The verdict: this is just a 27B model!
Let that sink in for a second. This isn't a frontier API model with a hundred billion parameters and unlimited context. It's:
- 27B parameters
- Q4 quantization (
UD-Q4_K_XL) - q8_0 KV cache
- Running on a single RTX 5090, ≈ 25.5 GB VRAM
And it produced a complete, polished, playable game in about an hour of autonomous work. Very capable. Local LLMs are not where they were even six months ago.
What's next
Two things:
- Next, I'm going to run this same model through our Cowork module — our own agentic harness that we're building and releasing soon. It handled Pi surprisingly well on its own, so I'm really curious how it performs inside our proper harness.
- For production, I don't think Unsloth is the right fit — it's great for dev and experimentation, but for a real serving setup I'd rather stand up a dedicated machine running SGLang or vLLM. That's the plan.
Stay tuned!